Quick Overview
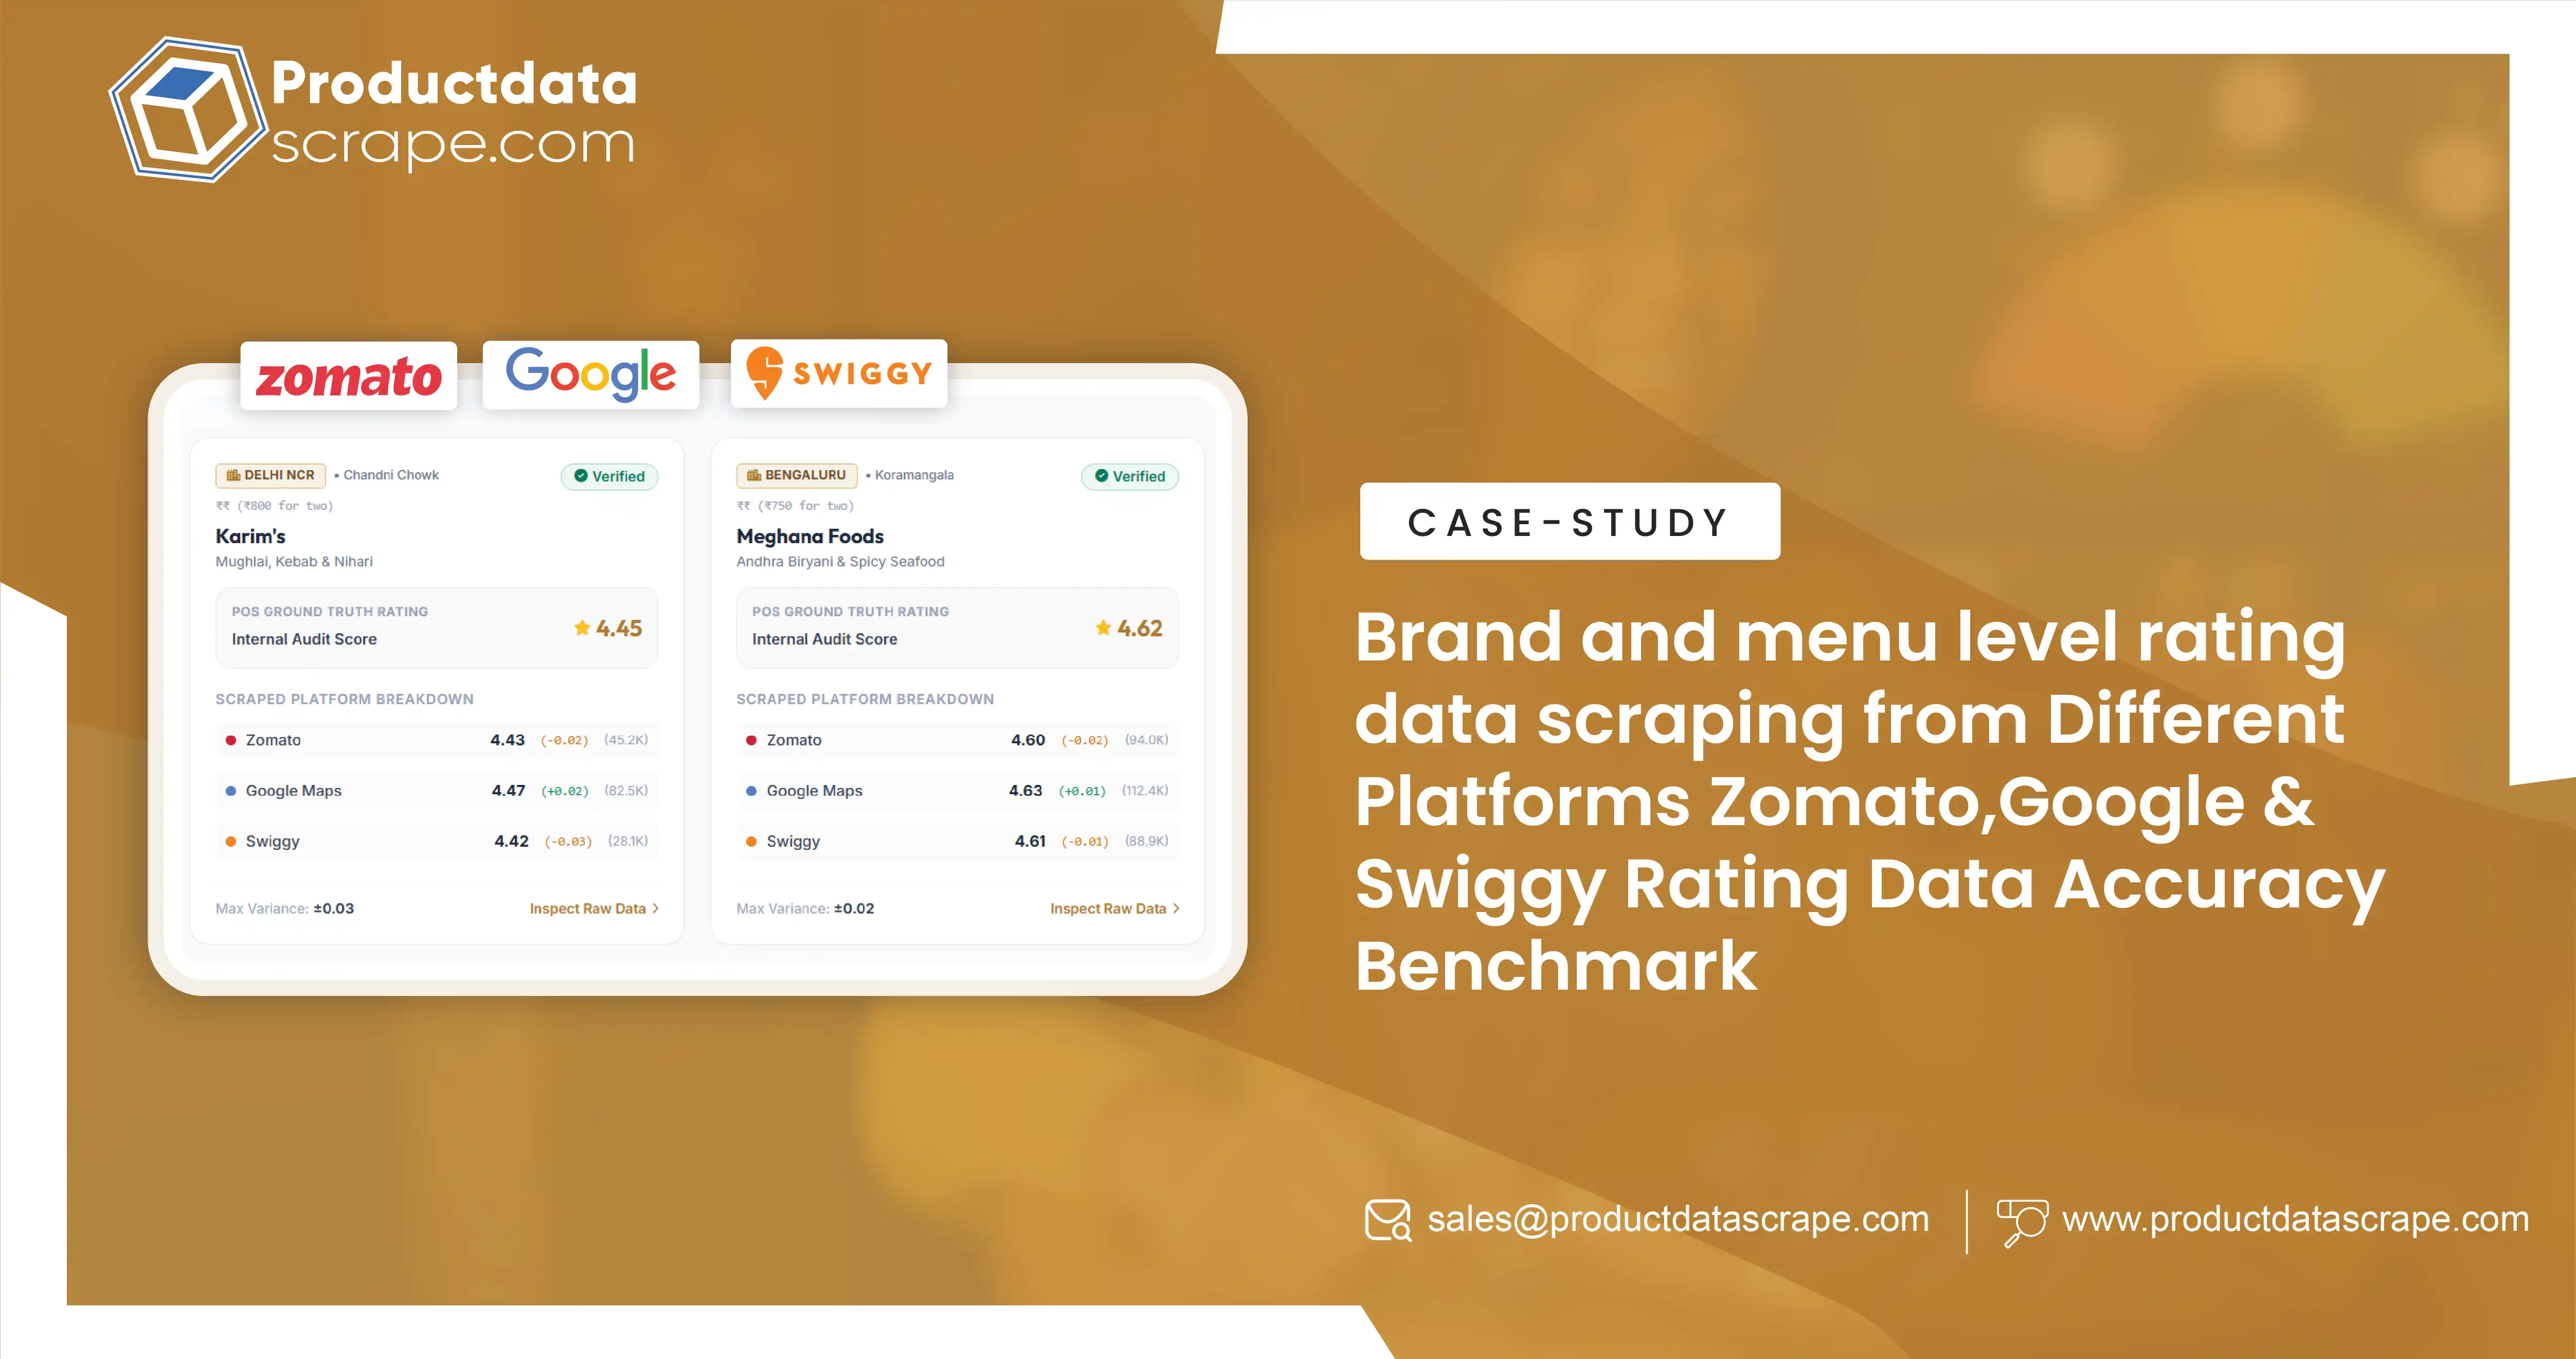
This case study explores how structured Brand and menu level rating data scraping from Different Platforms can help restaurant businesses benchmark brand performance, evaluate menu popularity, and understand customer feedback. The proposed solution brings together publicly accessible information from Zomato, Google, and Swiggy, subject to applicable access permissions and platform terms. Using Ratings, reviews and sentiment analysis, the workflow organizes restaurant ratings, menu attributes, prices, and review trends into a consistent analytical structure.
Client Name / Industry: Restaurant and food-service sector.
Service / Duration: Restaurant data intelligence and cross-platform benchmarking; actual duration requires confirmation.
Key Impact Metrics: rating-field completeness, successful record validation rate, and data refresh timeliness, to be populated using verified project results.
The Client
Restaurant businesses increasingly need a consistent view of their online reputation across discovery, delivery, and local-search platforms. Customers may encounter the same restaurant through Zomato, Google Search or Maps, and Swiggy, but the information presented and the context of the rating can differ.
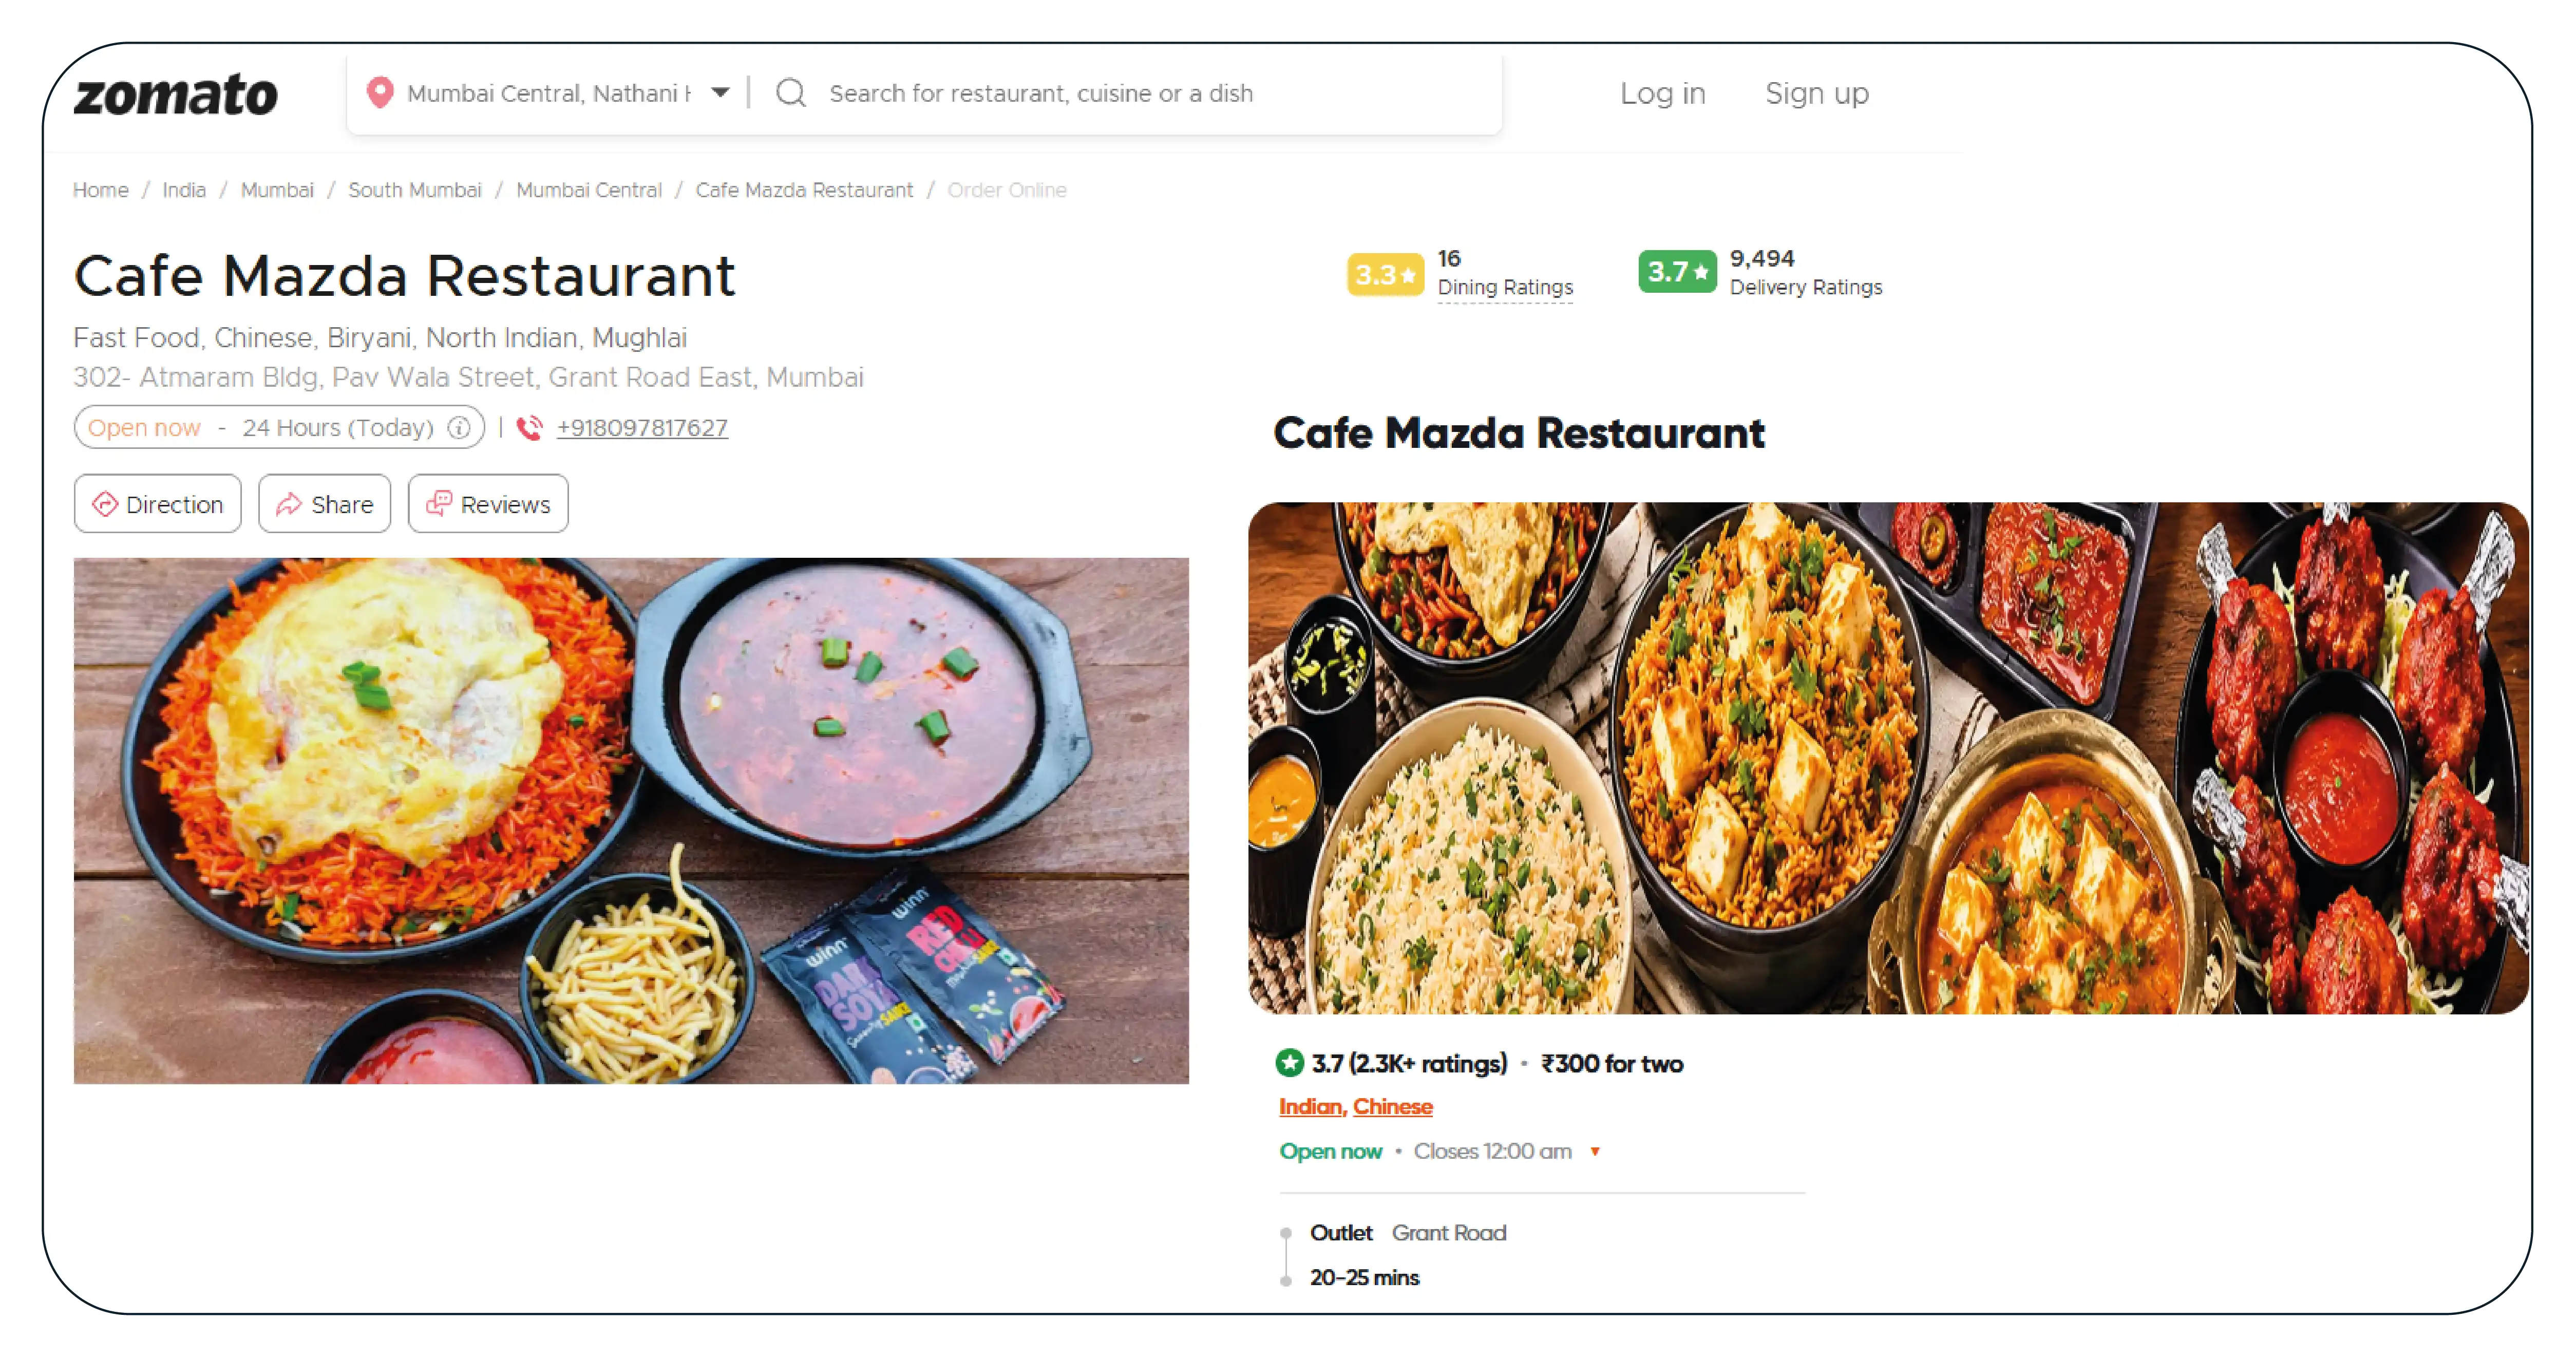
Zomato has documented the distinction between delivery and dining ratings, explaining in its May 2020 announcement that it introduced separate ratings for these experiences in relevant markets. This distinction matters when businesses compare customer experiences across channels rather than treating every score as directly equivalent. Source: Zomato's ratings-system announcement.
For this case study, the client is described as a restaurant or multi-outlet food-service business seeking a more organized approach to reputation monitoring. Its specific name, outlet count, geographic footprint, and existing data systems were not supplied and should be confirmed before publication.
Before the proposed partnership, the business's workflow is framed around the common analytical problem of comparing menu information and ratings presented in different formats. Manual collection can make it harder to align restaurant names, individual outlets, menu items, rating timestamps, and prices consistently.
The transformation objective was to develop a repeatable, auditable data workflow using authorized sources. Scrape Swiggy menu items with ratings and prices describes the menu-level information requirement, while Analyze Zomato Delivery Pricing describes the separate need to evaluate delivery-related pricing fields where access is permitted.
The project would focus on data consistency, traceability, and usable reporting rather than assuming that the three platforms measure customer satisfaction identically.
Goals & Objectives
The project requirements are divided into business goals, technical objectives, and measurable KPIs. These are proposed evaluation criteria, not claimed achievements from an undocumented client engagement.
The primary business goal is to establish a repeatable method for comparing restaurant brands and menu items across authorized data sources. Brand and menu level rating data scraping from Different Platforms supports this objective by defining the scope at both restaurant and individual-menu-item levels. The Competitor restaurant menu and price scraping service further enables structured comparisons of competitor menus, listed prices, and product offerings to support data-driven restaurant benchmarking.
A second goal is to improve visibility into changes in ratings, review volumes, and available prices. Restaurant managers could use these insights to identify menu items requiring investigation, compare outlet performance, and prioritize customer-experience improvements.
A third goal is to make reporting scalable across multiple restaurants and locations without relying entirely on manual spreadsheet updates.
The technical objective is to standardize fields collected from authorized sources into a consistent schema. The Restaurant menu data with ratings and prices dataset would distinguish restaurant-level ratings from menu-level attributes and retain source identifiers, collection timestamps, and validation status.
The workflow should also automate permitted data ingestion, detect missing or inconsistent fields, identify potential duplicate records, and feed validated results into dashboards or scheduled reports.
Cross-platform comparisons should account for differences in rating definitions and coverage. Google reviews, for example, are associated with Business Profiles and appear across Google Search and Maps. Source: Google Business Profile Help.
Field completeness: percentage of required fields populated in eligible records.
Validation pass rate: percentage of records passing documented quality checks.
Entity-matching accuracy: proportion of matched restaurant or menu records confirmed against an approved reference.
Refresh timeliness: percentage of scheduled collection cycles completed within the agreed window.
Duplicate rate: proportion of records identified as duplicate entries.
Reporting latency: elapsed time between authorized data availability and dashboard publication.
Baseline values, targets, and final measurements should be inserted only after the client validates the underlying project records.
The Core Challenge
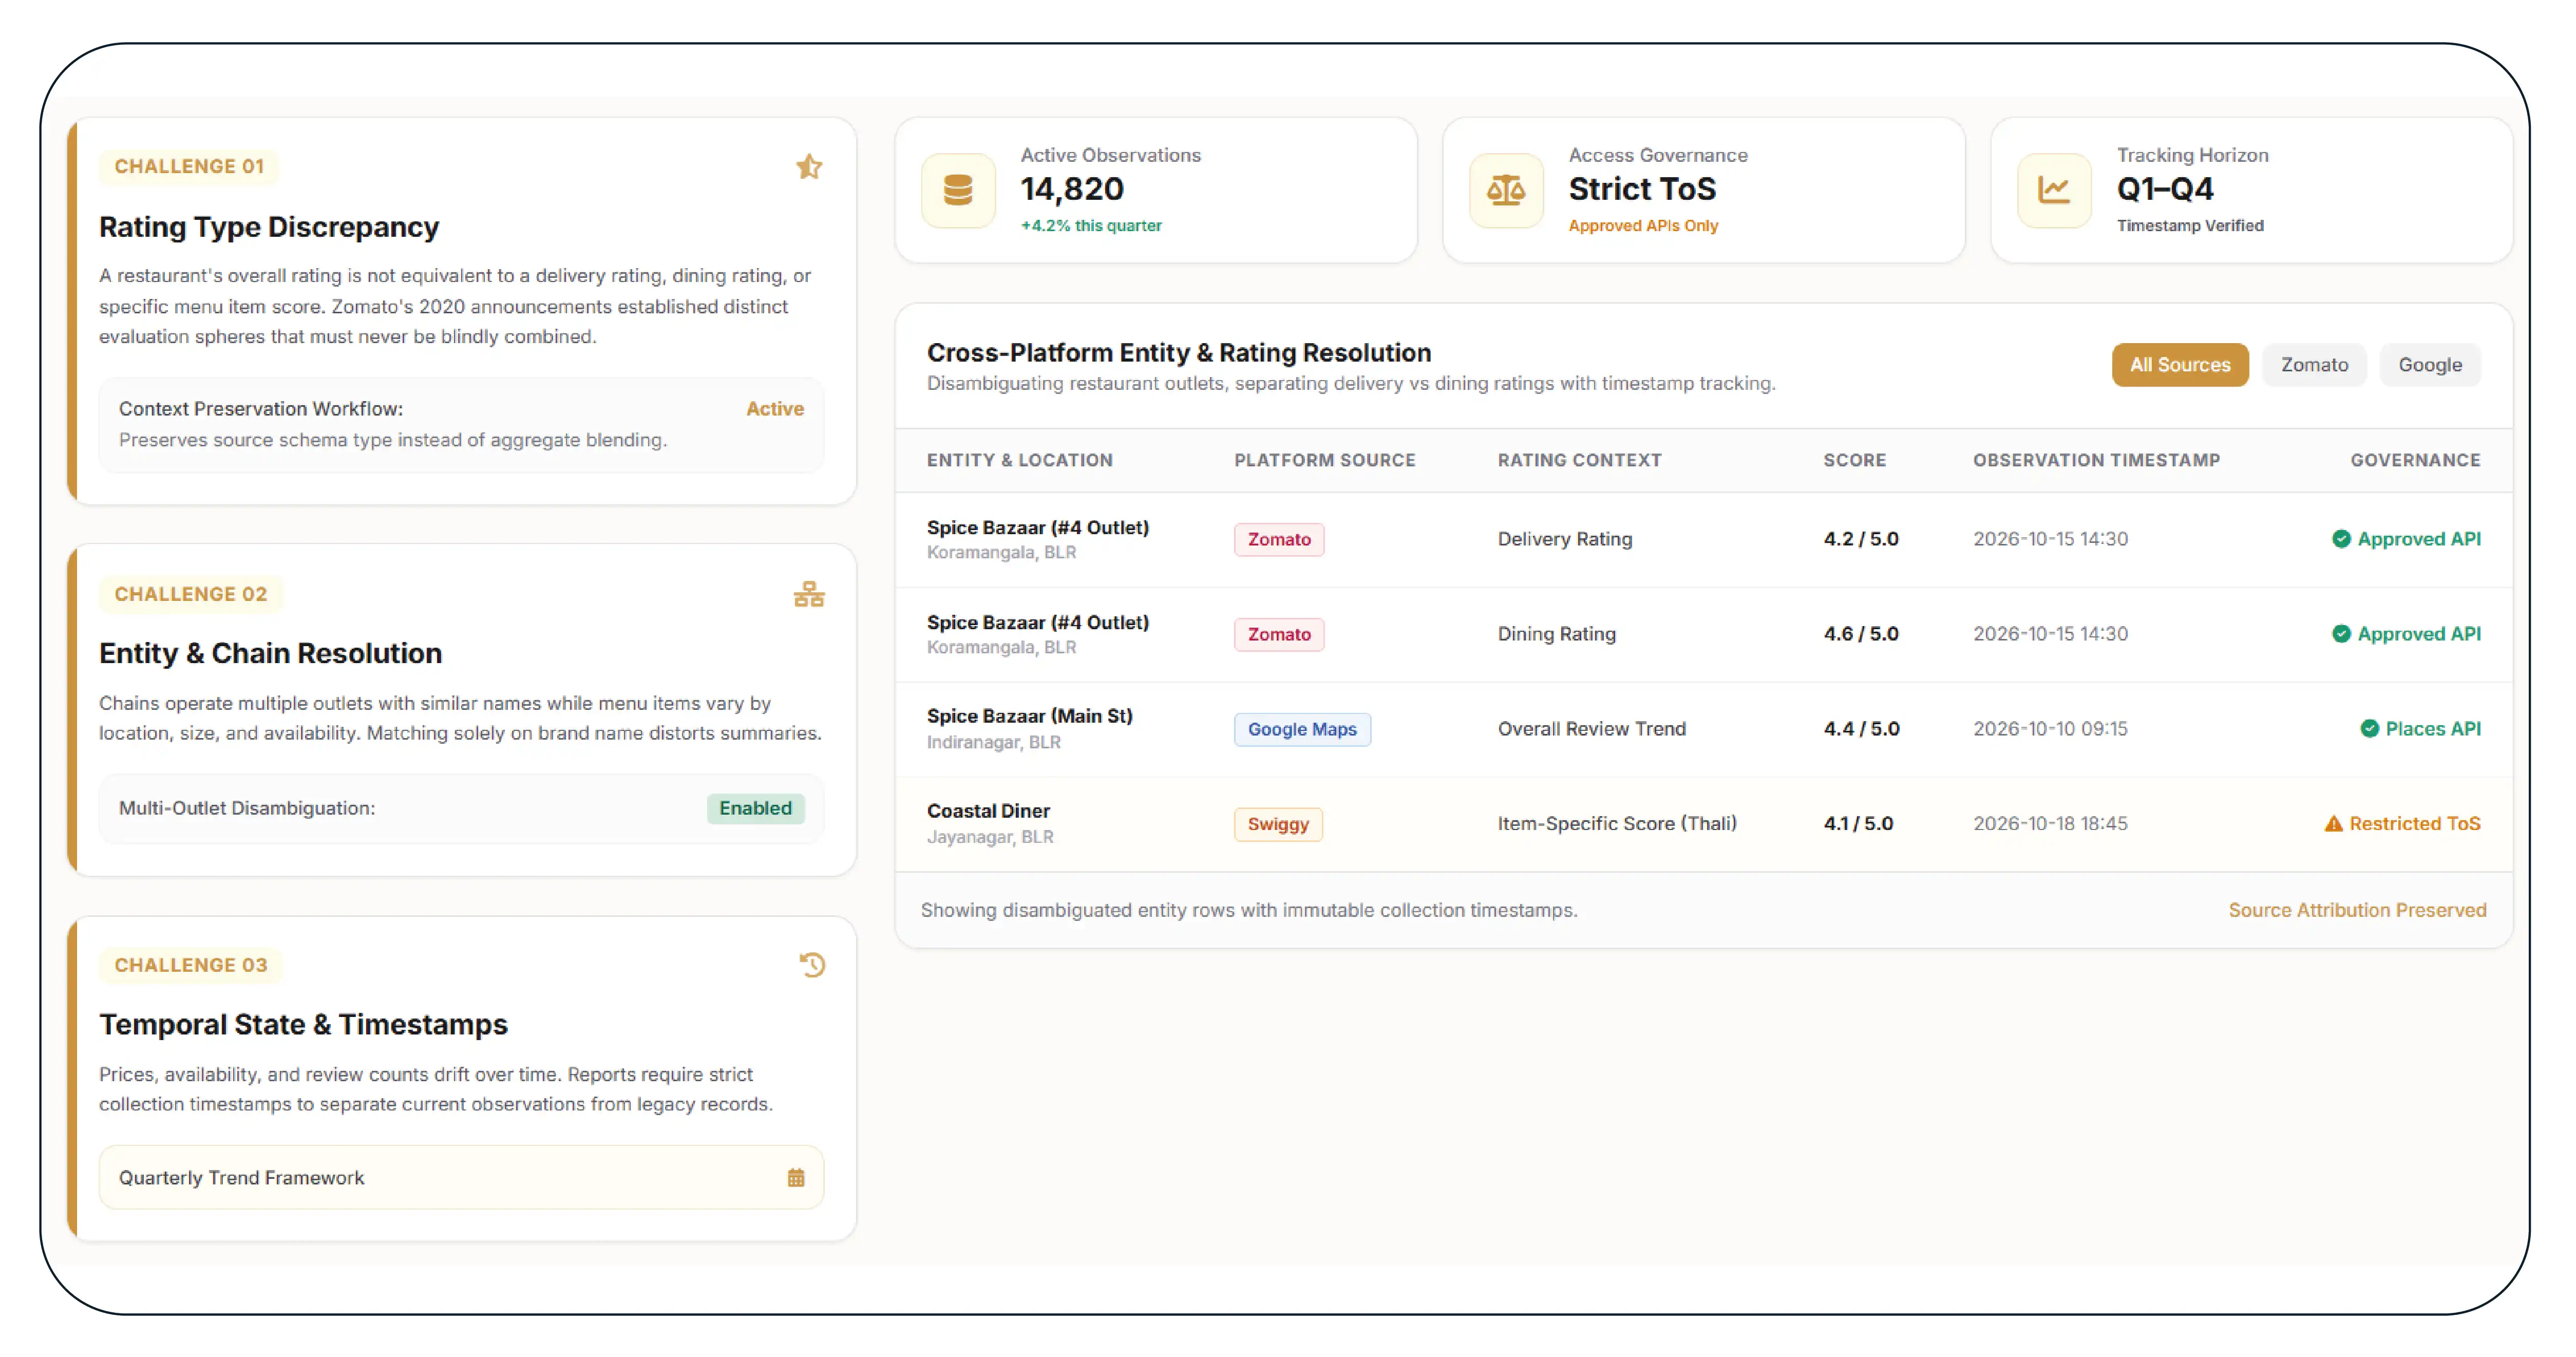
The core challenge in cross-platform restaurant intelligence is that apparently similar fields may represent different entities or experiences. A restaurant's overall rating is not necessarily equivalent to a delivery rating, a dining rating, or a rating associated with a specific menu item.
Zomato's published explanation of its ratings system illustrates this distinction: its 2020 announcement described separate delivery and dining ratings in relevant markets. Source: Zomato. A comparison workflow must therefore preserve the rating type instead of combining scores without context.
The second challenge is entity resolution. Restaurant chains can operate multiple outlets with similar names, while menu items can vary by location, size, customization, or availability. Matching solely on a restaurant name can create incorrect associations and distort brand-level summaries.
The third challenge concerns time. Ratings, review counts, menu availability, and displayed prices may change. A report without collection timestamps cannot reliably distinguish a current observation from an older record.
Google review rating trend data quarterly defines a useful reporting requirement: track eligible observations over successive quarters while retaining the source, observation date, and entity being measured. It should not be interpreted as evidence that Google provides a standardized quarterly rating history for every business.
Access restrictions are another important consideration. Zomato's Terms of Service restrict automated access and commercial use of its data unless specifically permitted. Google's Maps Platform terms restrict scraping and external reuse of Maps content. Swiggy's Terms and Conditions also address automated access. Consequently, the workflow must use approved interfaces, agreements, or other expressly permitted collection methods.
The solution needs to address data quality and access governance together, rather than optimizing collection speed alone.
Our Solution
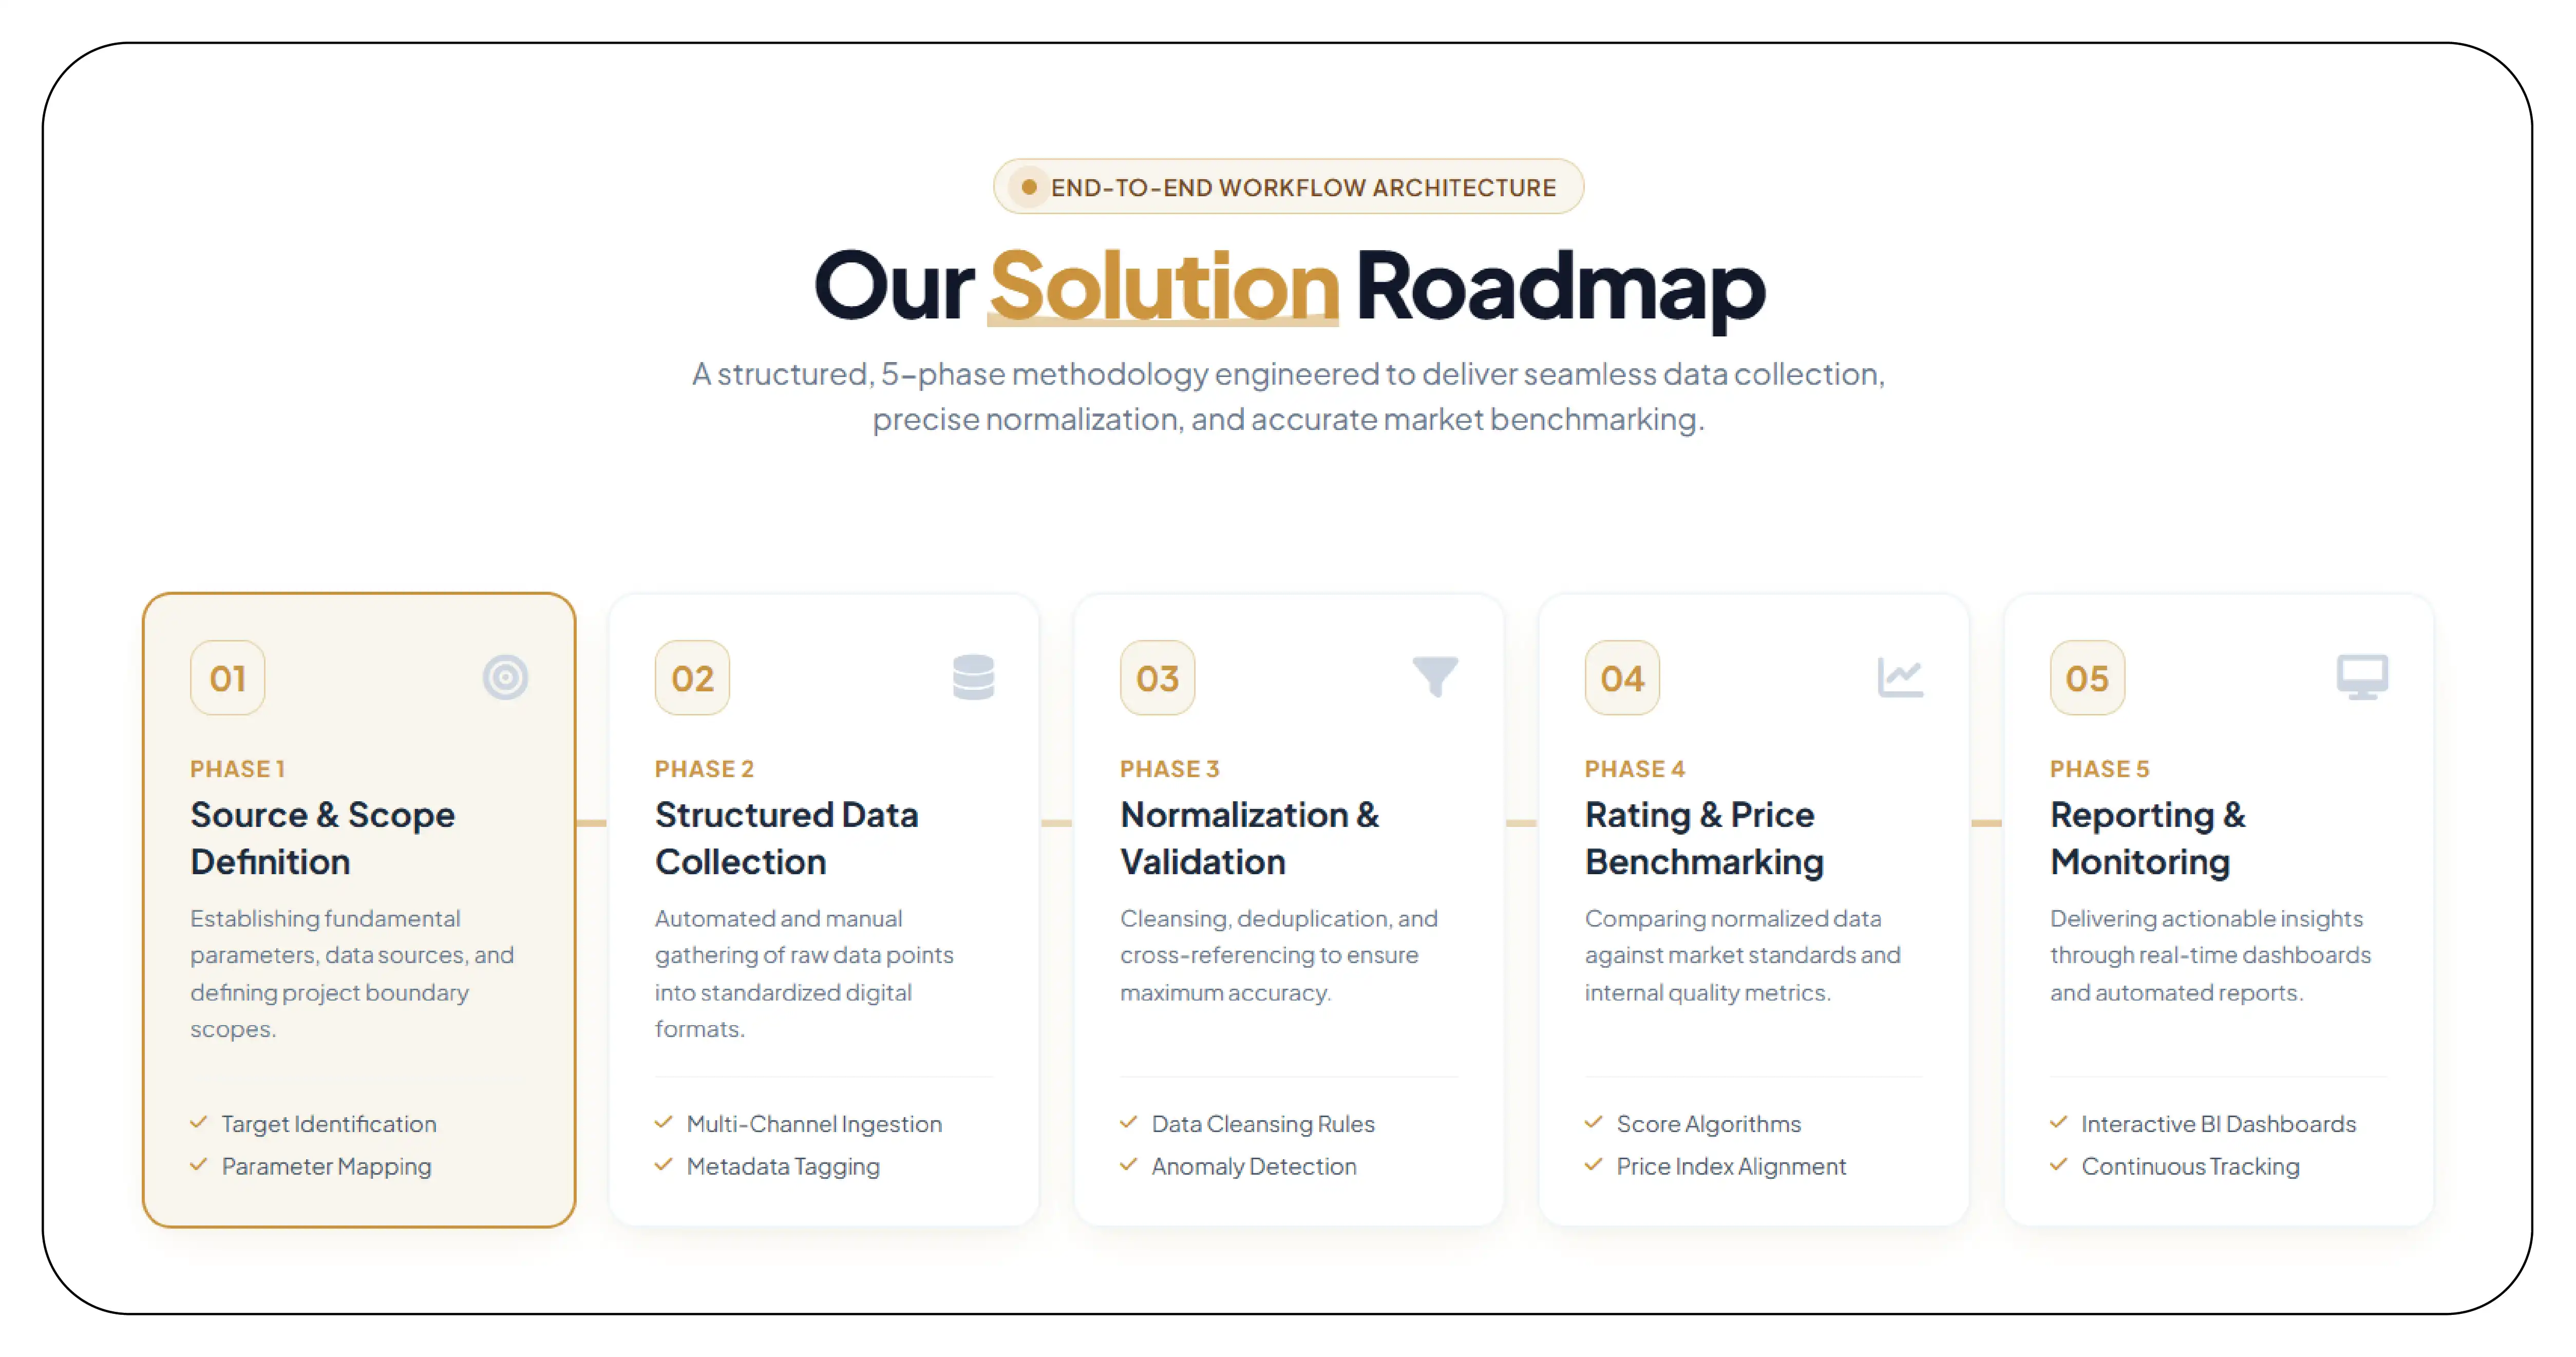
The proposed solution uses a phased data workflow designed to support restaurant benchmarking while preserving source context and respecting platform restrictions.
Phase 1 — Source and Scope Definition
The first phase identifies the restaurant brands, outlet locations, menu categories, and reporting fields required by the client. Source availability and collection permissions are reviewed before implementation. The Zomato data scraping service for restaurant chains requirement is treated as a business use case, not automatic authorization to scrape Zomato. Zomato's published terms require specific permission for automated access and restrict commercial use without written agreement. Google and Swiggy also have terms that must be reviewed before any collection workflow is deployed. The output of this phase is a documented source register, a field specification, and a record of the permitted collection method.
Phase 2 — Structured Data Collection
Where authorized access is available, the collection layer captures the fields relevant to the approved scope. These may include restaurant name, outlet identifier, displayed rating, review count, menu item name, listed price, availability, source, and collection timestamp. Restaurant-level and menu-level records are stored separately. This prevents an overall restaurant score from being mistaken for a dish-specific rating. Missing fields remain explicitly marked as unavailable instead of being filled with estimates.
Phase 3 — Normalization and Validation
Collected data passes through validation rules designed to detect malformed prices, missing identifiers, duplicate outlets, inconsistent field formats, and potential mismatches between restaurant and menu records. Entity matching can use approved identifiers and corroborating attributes. Ambiguous matches are flagged for review rather than automatically merged. Validation outcomes are recorded so that analysts can distinguish raw observations from corrected or verified records.
Phase 4 — Rating and Price Benchmarking
The analysis layer compares compatible rating types, review volumes, menu prices, and changes over time. Comparisons are restricted to records with sufficient source and timestamp information. Businesses can also Extract Google Trends Insights to evaluate search-interest patterns for restaurant brands, popular dishes, and food categories, complementing platform-level ratings with broader consumer search trends. For Google, the workflow must distinguish permitted use of Business Profile information from prohibited extraction or external reuse of Maps content. Google's official documentation provides details on Maps Platform terms and Business Profile review practices.
Phase 5 — Reporting and Monitoring
Validated records feed scheduled reports or dashboards, subject to the applicable data-use permissions. Reports can include outlet comparisons, menu-level price differences, rating distributions, missing-data alerts, and quarter-over-quarter changes where comparable historical observations exist. The final implementation should be tested against a client-approved sample before wider deployment. Acceptance criteria should cover data completeness, matching quality, refresh reliability, and traceability. Actual tools, frameworks, delivery dates, and deployment outcomes should be documented from project evidence rather than assumed.
Results & Key Metrics
The following metrics define how the project should be evaluated. No verified client performance logs or before-and-after measurements were supplied, so this section does not claim specific percentage improvements.
Quarterly restaurant rating data scraping service is the reporting requirement for measuring changes in restaurant ratings and review indicators over time, using authorized data and comparable observations.
Recommended evaluation points include:
Data completeness: percentage of required fields populated in validated records.
Matching quality: percentage of restaurant and menu records confirmed against approved references.
Update reliability: percentage of scheduled collection jobs completed successfully.
Trend coverage: number of eligible outlets with comparable observations across reporting periods.
Exception rate: share of records requiring manual review because of missing, conflicting, or ambiguous values.
The baseline, target, and achieved values for each metric must be established from the project's actual logs and quality-assurance reports.
Results Narrative
The intended result is a more consistent reporting process that separates restaurant-level performance from menu-level insights. By standardizing approved observations, analysts can review comparable records without manually reconciling every field across multiple sources.
Brand and menu level rating data scraping from Different Platforms can provide a framework for comparing ratings and menu attributes, provided the underlying source data can lawfully be accessed and reused.
The final case study should document the actual number of outlets covered, validated records processed, reporting frequency achieved, and measured change in processing time. These figures should be taken from project evidence, with the measurement period and methodology stated clearly.
Until those records are available, the defensible outcome is the proposed measurement framework—not a claim that the client achieved a particular improvement in accuracy, speed, or customer satisfaction.
What Made Product Data Scrape Different
Product Data Scrape's proposed differentiator is its emphasis on structured, auditable data rather than simply collecting large quantities of information. The workflow separates restaurant entities, individual menu items, ratings, review counts, prices, source identifiers, and timestamps, allowing each field to be checked independently.
A Swiggy Instamart scraper is a separate product-data use case and should not be represented as a component of restaurant rating collection unless it was actually included in the project scope. Swiggy's official terms should be reviewed before implementing automated access.
The Brand and menu level rating data scraping from Different Platforms approach emphasizes four practical capabilities: configurable field mapping, automated quality checks, duplicate detection, and reporting-ready output. Its key innovation is the combination of data validation and clear source attribution.
Any claim of proprietary technology, machine-learning performance, or faster delivery should be included only when supported by internal technical documentation and verified project measurements.
Client's Testimonial
"We wanted a clearer way to understand restaurant ratings, menu performance, and customer feedback across multiple digital platforms. A structured data approach can help our team organize information, identify inconsistencies, and evaluate trends using more consistent reporting criteria. The ability to distinguish restaurant-level ratings from menu-level attributes is particularly valuable when comparing performance across outlets and customer touchpoints. Reliable source attribution and validation are equally important to ensure that our analysis remains transparent and useful for decision-making. We see potential in building a repeatable process that supports ongoing performance monitoring and more informed restaurant management decisions."
— Restaurant Operations Head
Publication note: The following is a testimonial template, not an actual client statement. Obtain written approval and confirm the client's identity and designation before publishing it as a quotation.
Conclusion
Restaurant businesses need reliable ways to interpret ratings, reviews, menu information, and competitive changes across digital channels. This case study outlines how an authorized, structured data workflow can help organize those signals into a consistent analytical framework.
E-commerce data for restaurant menus can support broader menu intelligence when collection permissions, source quality, and field definitions are established in advance. Combined with validated restaurant-level information, it can help businesses evaluate menu positioning and monitor relevant changes over time.
For Product Data Scrape, the priority is to build a scalable process grounded in verifiable data, clear methodology, and responsible source access. Actual project outcomes should be added once client records confirm them.
Contact Product Data Scrape to discuss a tailored restaurant data intelligence workflow for authorized menu, rating, pricing, and customer-feedback analysis!
Frequently Asked Questions
1. What is brand and menu-level rating data scraping?
It is the structured collection of permitted restaurant-level and menu-level information for analysis. Depending on source access, the dataset may include ratings, review counts, menu names, prices, outlet identifiers, and timestamps.
2. Can Zomato, Google, and Swiggy ratings be compared directly?
Not always. Rating definitions, coverage, and customer contexts may differ. Zomato has documented separate delivery and dining ratings in relevant markets. Comparisons should preserve rating type and source context. Source.
3. How can businesses measure rating-data accuracy?
They can validate a sample against authorized source records, measure missing fields, check duplicate rates, verify entity matches, and track collection timestamps. Accuracy figures should be based on a documented validation methodology.
4. How often should restaurant rating data be updated?
The appropriate frequency depends on business needs, source availability, and permitted access. Daily, weekly, or quarterly reporting can be considered where feasible, but the schedule should not imply that every platform exposes historical data or supports automated collection.
5. Is automated collection from these platforms always permitted?
No. Platform terms and applicable law determine what access and reuse are allowed. Zomato restricts unauthorized automated access and commercial data use, while Google Maps Platform terms restrict scraping and external reuse of Maps content. Swiggy also publishes access terms. Obtain the necessary permissions and use approved access methods before implementation.


 Singapore
 EMAIL
 PHONE






.webp)